


The Work Passed. Who’s Ready to Review?
Plain-English premise: AI can make today’s work better without telling you whether the person doing it is getting better. That second question needs its own evidence.
Judgment Seat: The future reviewer: the newer colleague whose judgment is still forming, and the lead deciding when to trust it.
👋 Last week’s closing promised an episode about the tasks that once formed future judgment, and what happens when they’re the first ones automated. The research changed my mind again. It didn’t establish that AI is quietly removing the practice that turns a newcomer into a reviewer. It showed something more useful: better work with AI and a more capable person without it are two different results, and the way the help works shapes which one you get.
Research Binder: the receipts (citations + source notes) are compiled in a PDF at the bottom of this post.
⚡ Pressure
AI can finish the first pass before a newer colleague has learned how to judge one.
🎯 Payoff
This issue gives you the Reviewer Bench Inventory: six questions that locate where newer colleagues practice judgment, get feedback, and get checked without the tool.
Pressure Moment
In late August 2026, Business Insider and Forbes reported that Valon, an AI startup, told most of its new hires to learn the job without AI until their manager was confident they could tell when the AI was wrong. Engineers were exempt, because all of their code already goes through peer review. According to the reporting, new hires had started asking tenured colleagues for help again.
That’s one company’s account, with no outcome data, and nothing in this issue supports restricting AI for newer people. What interests me is the test inside the policy. It didn’t ask whether new hires could produce good work with AI. It asked whether they could recognize when the AI was wrong, and it treated peer review as a place that question already gets answered.
I’ve stepped into a review and rewritten a backlog item myself because we needed to keep moving. The acceptance criteria got clearer, and the team had something it could use. What I hadn’t checked was whether the person who wrote it understood why I’d made those changes. I’d helped finish the work, but I’d left their learning unchecked.
Three Windows on the Same Work
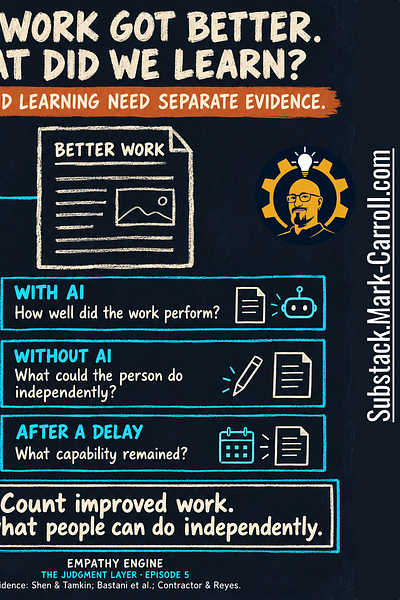
When the work improves, it’s natural to assume the person doing it improved too. That used to be a safe assumption, because the draft improved as the person drafting it improved. AI can separate the two, so every result in this issue answers one of three questions.
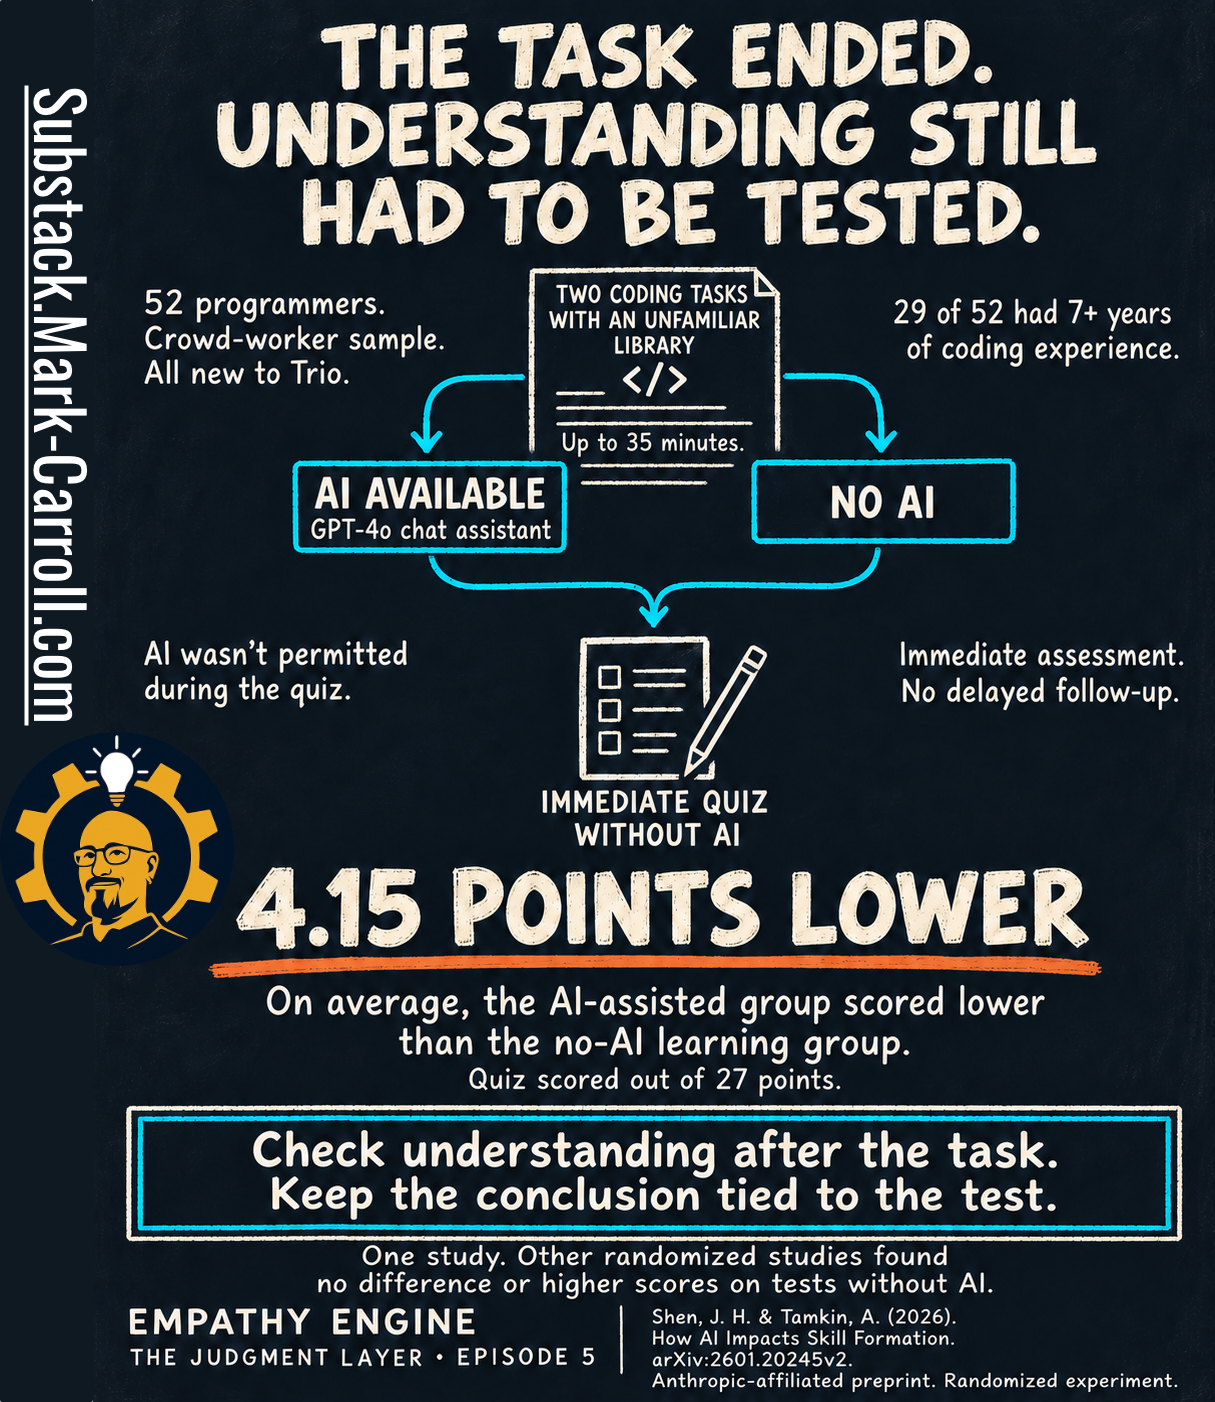
With AI, how well did the work perform? Without AI, what could the person do independently? After a delay, what capability remained? A successful output answers the first question. It doesn’t answer the other two, and when a team collects only output evidence, its development claim remains unchecked. Count improved work. Check what people can do independently.
This is where the episode separates from Episode Two, which asked whether the sender can explain the work at handoff. That’s still the right gate, but an explanation at handoff is evidence about that work on that day. It isn’t evidence that judgment is forming, and an explanation can be generated too.
The louder version of this story runs on hiring data: Stanford’s Digital Economy Lab found US employment for 22-to-25-year-olds in the most AI-exposed occupations about 19% below comparable less-exposed work, mostly through slower hiring, while a Danish study found no such effect. Those numbers describe who gets onto the bench, not what anyone on it is learning.
The Output Gain Is Real
Start with the first window, where the news is good. You’ve seen “Generative AI at Work” (Brynjolfsson, Li & Raymond, QJE, 2025) in earlier episodes; it’s back for a different reason. In a staggered rollout of an AI assistant to 5,172 customer-support agents, 89% of them working outside the US, resolutions per hour rose 15.2% across all agents and 36% in the lowest skill quintile, a subgroup of the same sample.
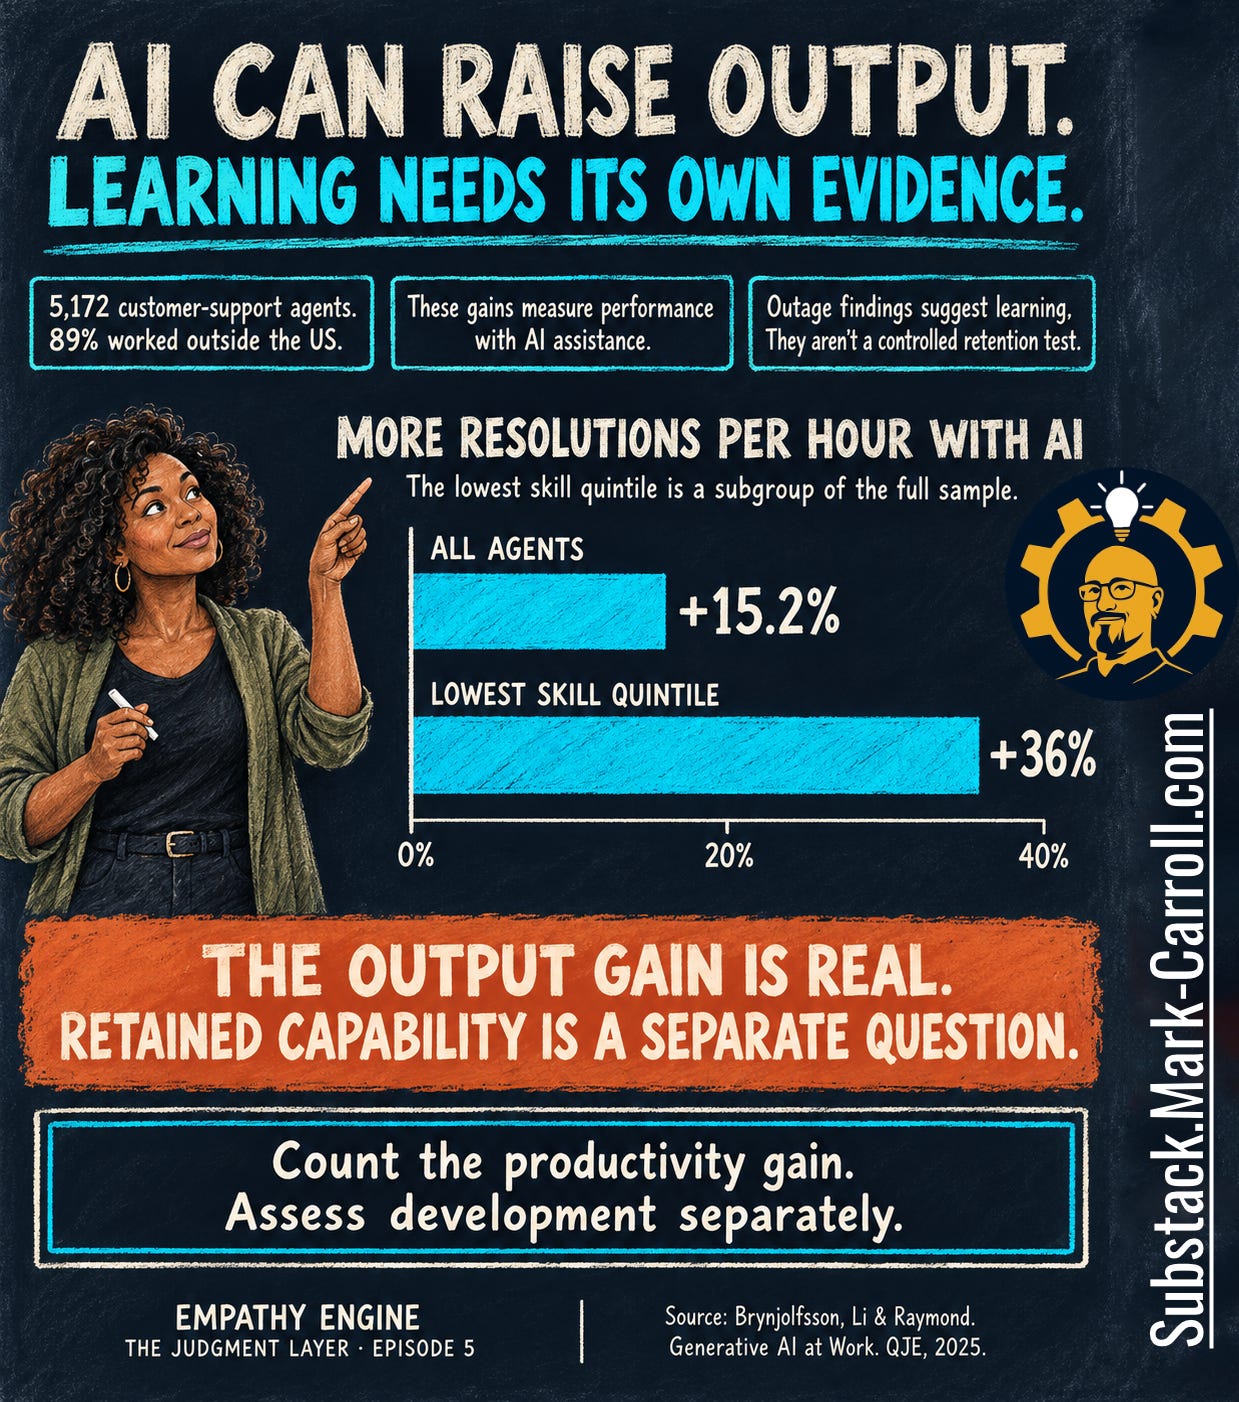
Every bar measures performance with AI assistance, though the study does hint at learning. Agents with AI reached in about two months the output untreated agents needed eight to ten months to reach, and during rare outages they stayed faster than their pre-AI baseline. The authors describe those outage results as consistent with durable worker learning.
That’s a real signal, but not a controlled retention test: outages were rare and may not have been random. The output gain is real. Retained capability is a separate question, so count the productivity gain and assess development separately.
The Task Ended. Understanding Still Had to Be Tested.
The second window opens when the AI leaves the room. Shen and Tamkin, “How AI Impacts Skill Formation,” a 2026 preprint by two Anthropic researchers, recruited 52 programmers from a crowd-worker platform, all new to Trio, an unfamiliar Python library. Everyone got two coding tasks and up to 35 minutes. Half could use a GPT-4o chat assistant and half couldn’t, and then everyone took an immediate quiz with AI not permitted.
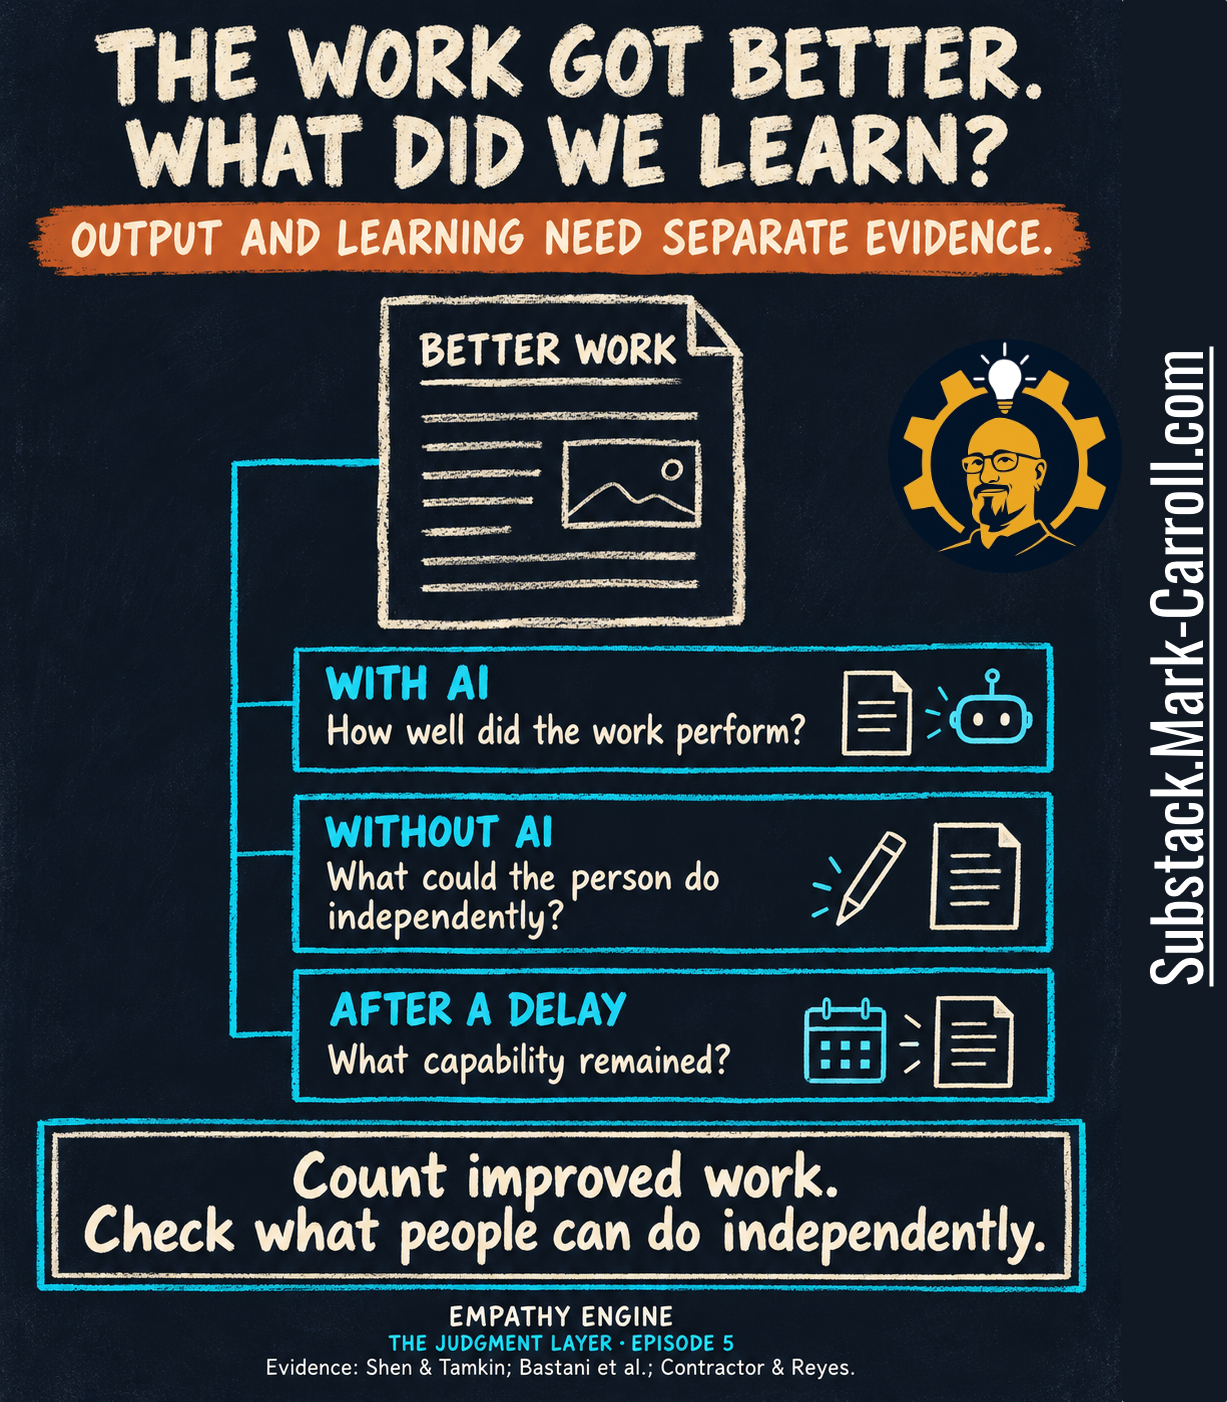
On average, the AI-assisted group scored 4.15 points lower on the 27-point quiz (d = 0.738, p = 0.010) and wasn’t significantly faster. Three cautions travel with that number. The sample was experienced, not junior: 29 of the 52 had seven or more years of coding, and only two per arm had one to three years. The quiz was immediate, so it can’t say what stuck. And it’s an Anthropic-affiliated preprint.
Its six usage patterns, where conceptual questioners outscored delegators, came from unrandomized groups of two to seven people, so they’re a clue, not a training method. Check understanding after the task, and keep the conclusion tied to the test.
Then the Evidence Pointed the Other Way
If the coding study were the whole story, this would be a warning and nothing more. Contractor and Reyes, “Experimental Evidence on the Learning Impact of Generative AI” (2026 preprint), randomized a US undergraduate sample to learn with AI allowed or forbidden, then tested everyone with AI and other resources barred. 211 students attended the first session, and 204 returned about a week later to answer new test items.
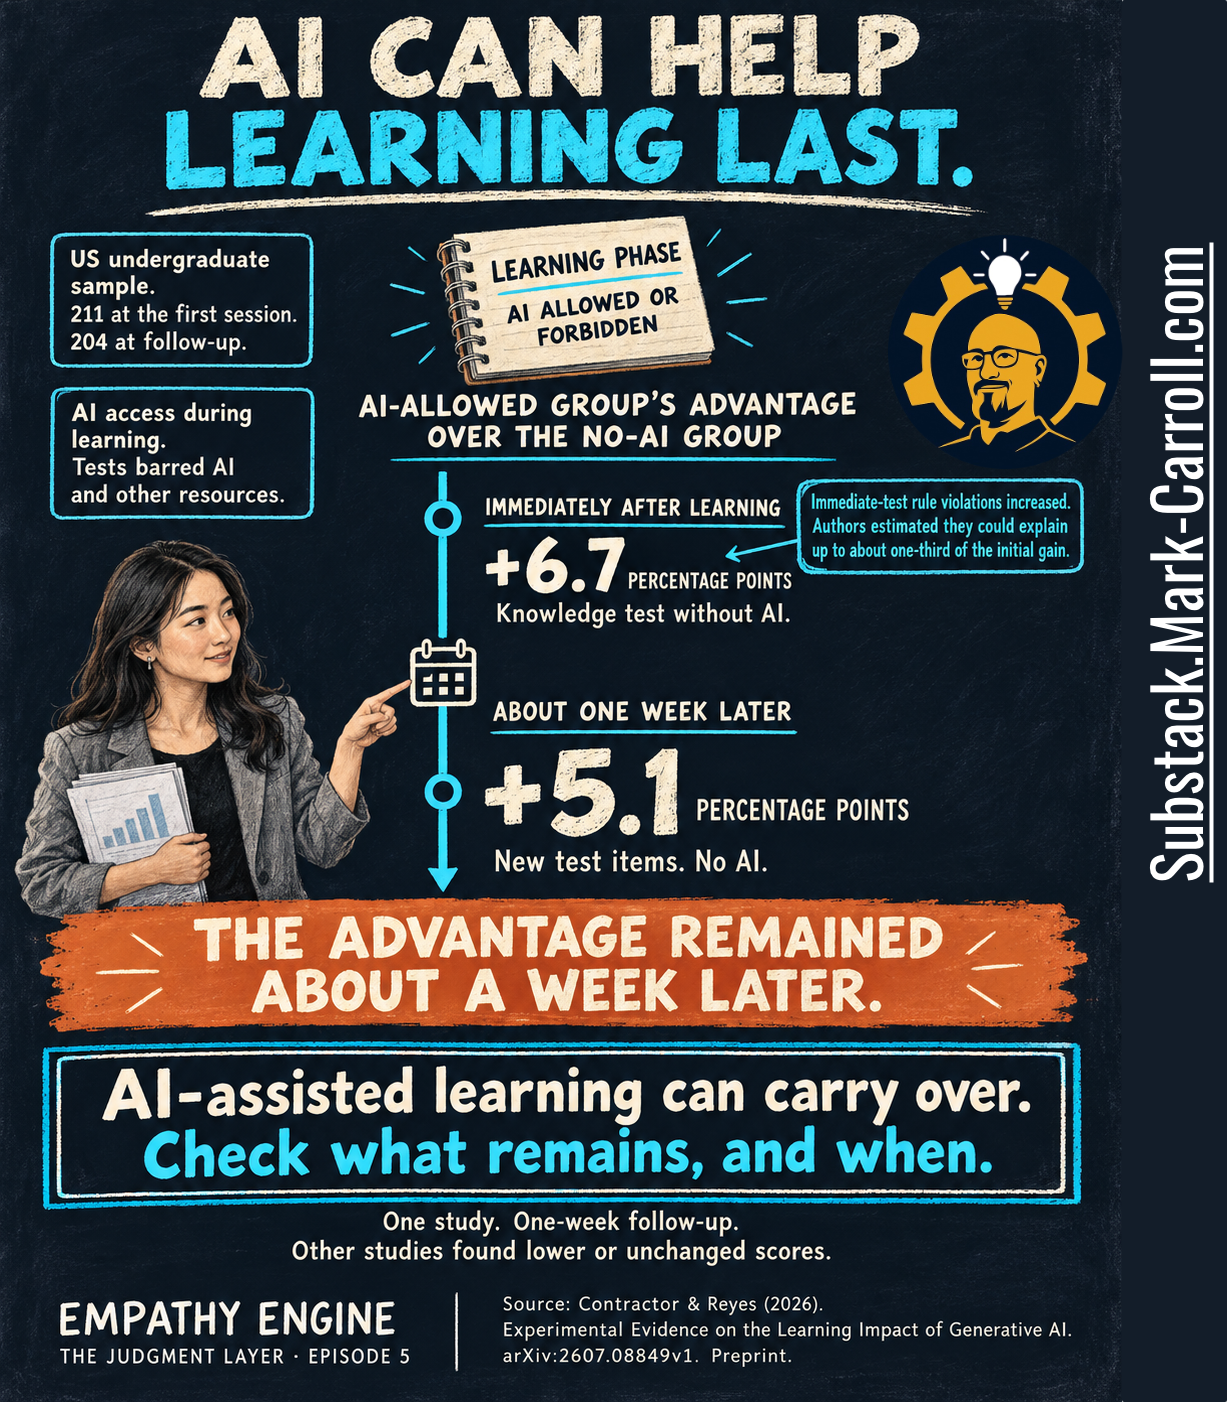
The AI-allowed group was 6.7 percentage points ahead immediately after learning and 5.1 points ahead about a week later. There’s a caveat on the first number: rule violations during the immediate test increased in the AI arm, and the authors estimated they could explain up to about one-third of the initial gain. The two figures are separate between-group estimates, not a measure of how much each student retained.
This is one study and one week, with undergraduates in a lab, on a different task and population from the coding study, so the two shouldn’t be averaged into a slogan. It does show that AI-assisted learning can carry over, which is why the third window is worth opening: check what remains, and when.
The Help Changed. So Did the Result.
A third experiment adds a distinction within one setting: the design of the assistance changed the outcome. Bastani and colleagues (”Generative AI without guardrails can harm learning,” PNAS, 2025) randomized nearly 1,000 high-school mathematics students in Turkey by classroom. Students practiced with GPT Base, an unguided chat assistant; with GPT Tutor, which used teacher-written hints and guardrails designed to guide rather than hand over answers; or without AI. Everyone then sat an exam without AI.
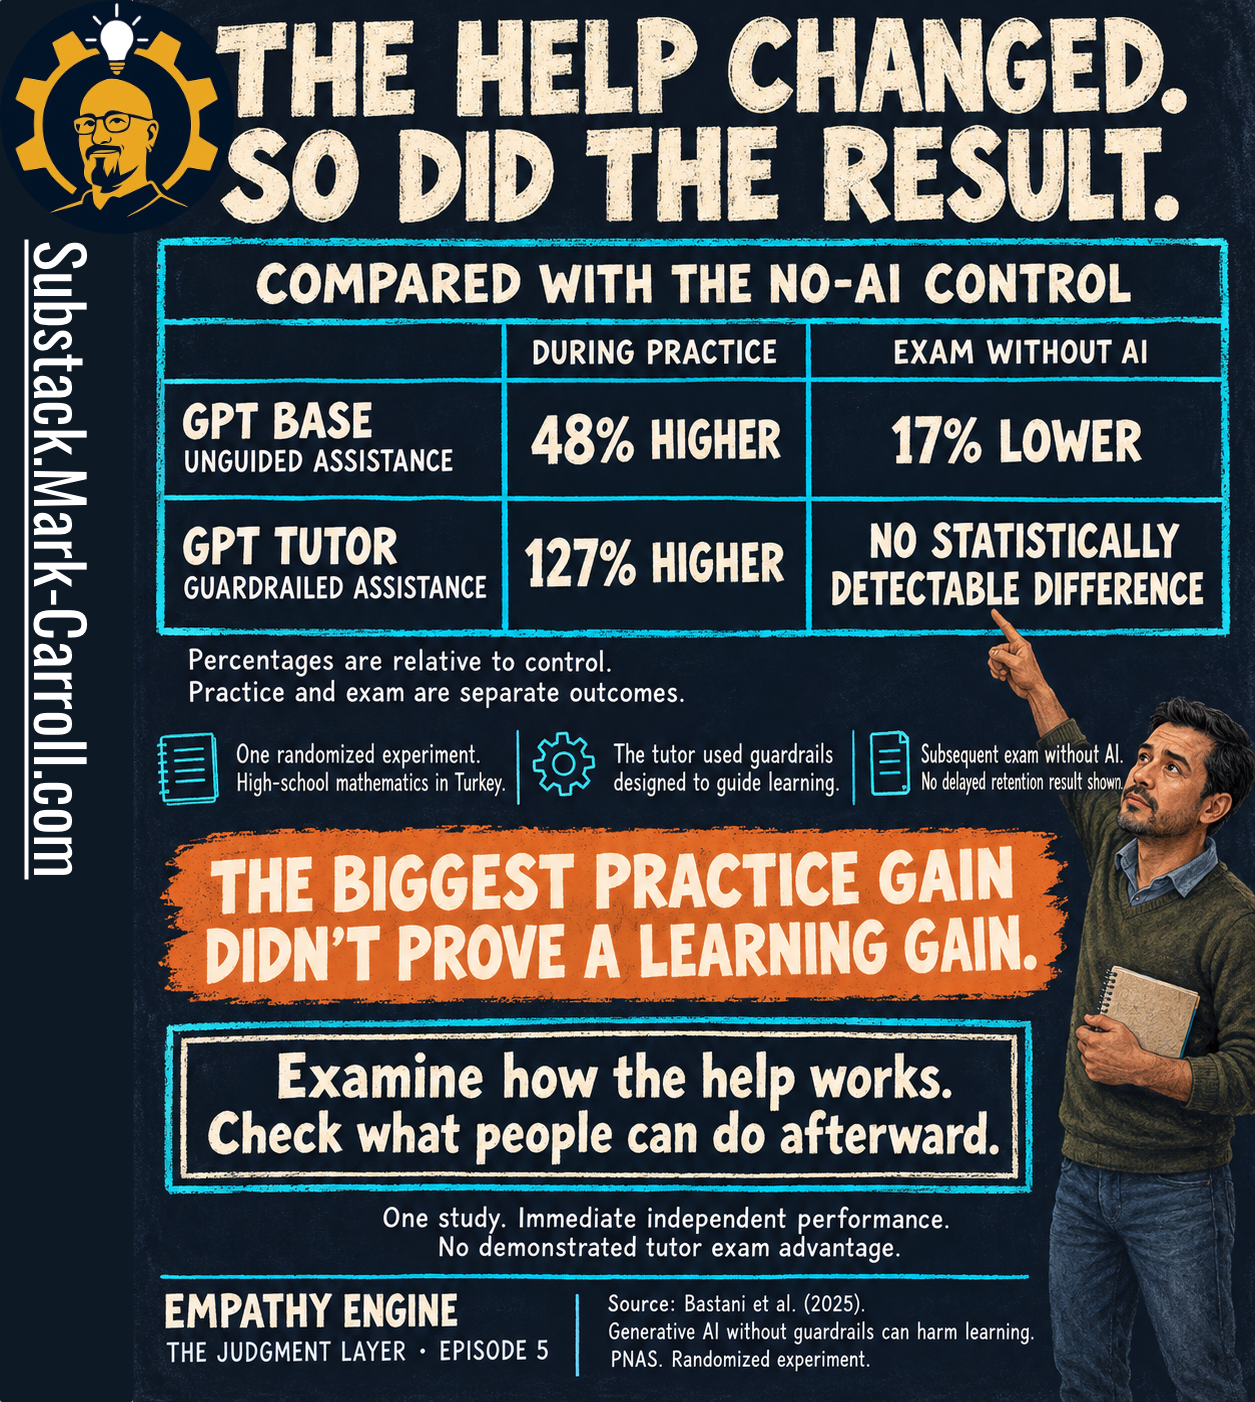
During practice, GPT Base students scored 48% higher than control and GPT Tutor students 127% higher. On the exam, GPT Base students scored 17% lower than control. GPT Tutor students showed no statistically detectable difference from control, and no demonstrated exam advantage either; the authors describe the guardrails as largely mitigating the harm. The biggest practice gain didn’t prove a learning gain.
One detail should bother anyone who picks tools by satisfaction scores: students preferred the unguided tool. It’s high-school math with no delayed result, so the percentages don’t transfer to a product team. The question does: examine how the help works, and check what people can do afterward.
Practice Needs the Right Support
If development isn’t automatic, what builds it? The nostalgic answer is to protect the grunt work, because it was the apprenticeship. Some of it was; some was repetition nobody ever looked at. Even review doesn’t teach by default: in a 2013 Microsoft study, Bacchelli and Bird coded only 12 of 570 code-review comments as knowledge transfer, though learning can happen in ways a comment code wouldn’t capture.
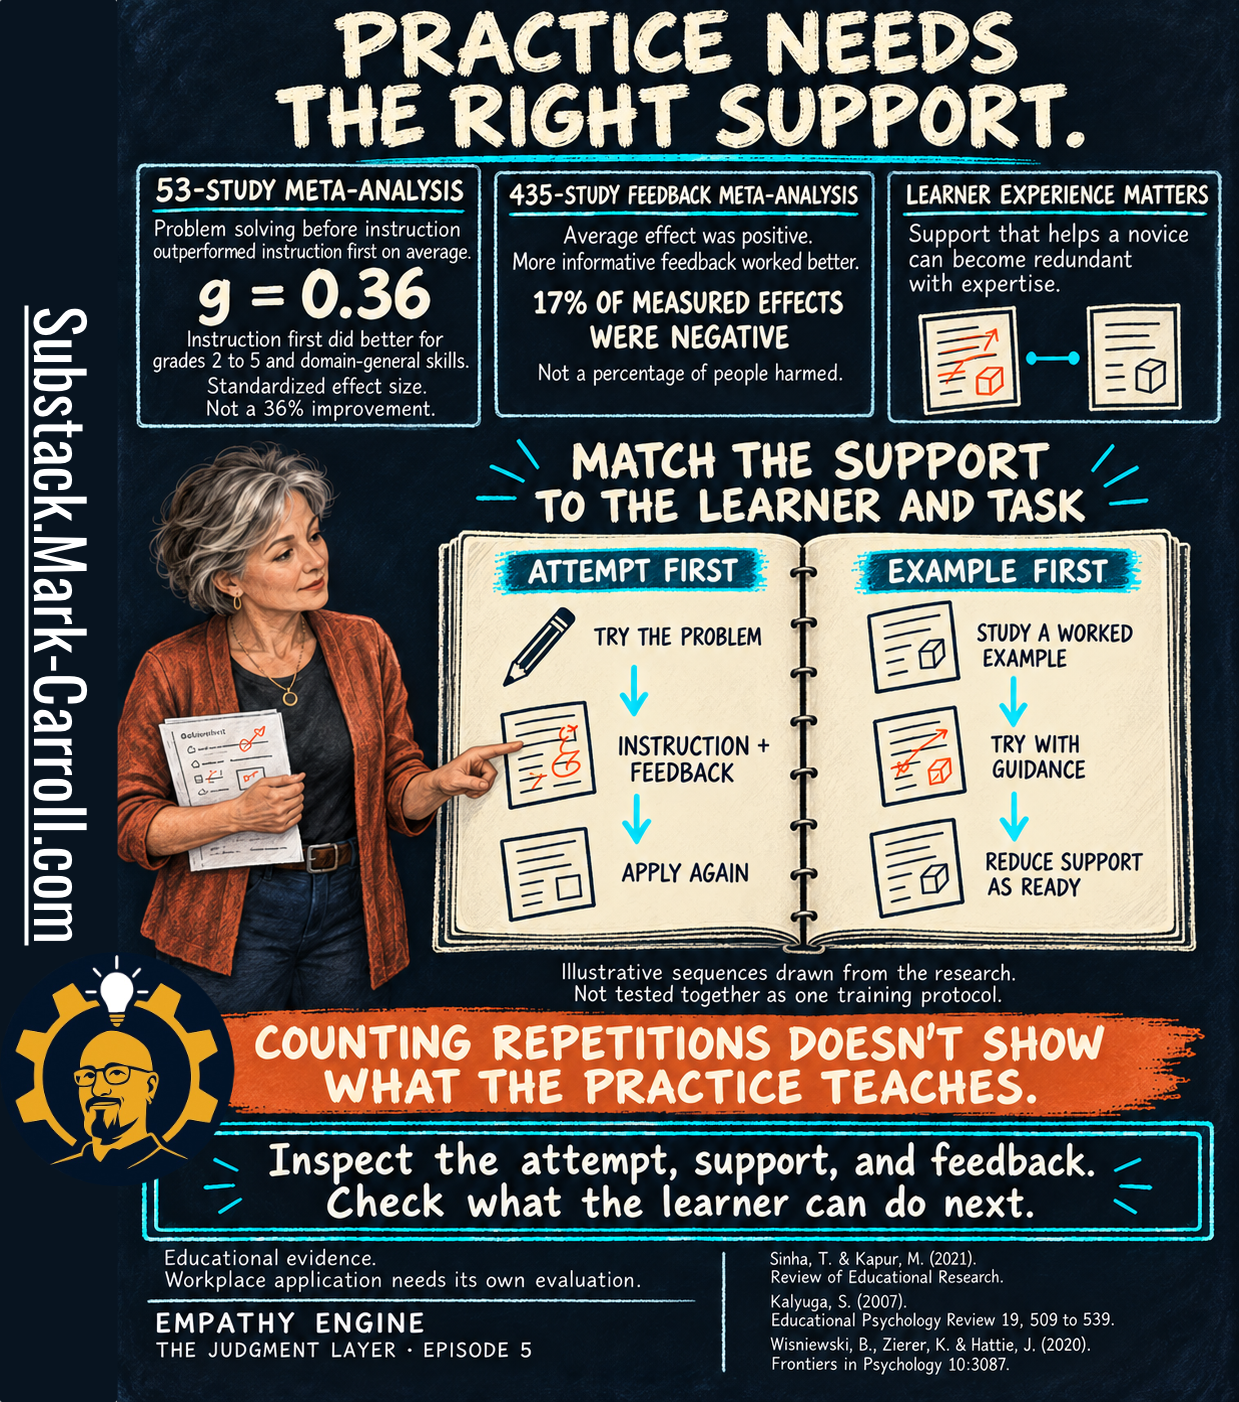
The chart’s three findings come from education, not workplaces. Sinha and Kapur’s 53-study meta-analysis found problem solving before instruction outperformed instruction first on average, g = 0.36, a standardized effect size rather than a 36% improvement, though instruction first did better for grades 2 to 5 and domain-general skills. Kalyuga’s expertise reversal research shows that support that helps a novice can become redundant as expertise grows; true beginners often learn more from a worked example. And Wisniewski, Zierer and Hattie’s 435-study meta-analysis found feedback helped on average and informative feedback helped more, while 17% of measured effects were negative, a share of effects rather than of people.
So the support has to match the learner and the task. The two sequences on the chart are illustrations, not a tested protocol. Counting repetitions doesn’t show what the practice teaches, and AI can either supply examples and feedback or do the attempt for the learner; only the workflow tells you which. Inspect the attempt, the support, and the feedback, and check what the learner can do next.
🧭 The Judgment Move
If the research can’t tell you whether your next reviewers are forming, your workflow can at least show you where they would be. The Reviewer Bench Inventory doesn’t measure anyone; it asks where, inside one consequential review task, a learner practices the judgment that task requires.
Orienting sentence: The Reviewer Bench Inventory is six questions about one consequential review task: what judgment it requires, where a learner attempts it, who gives feedback, what AI changed, where independent capability is checked, and who owns what’s unclear.
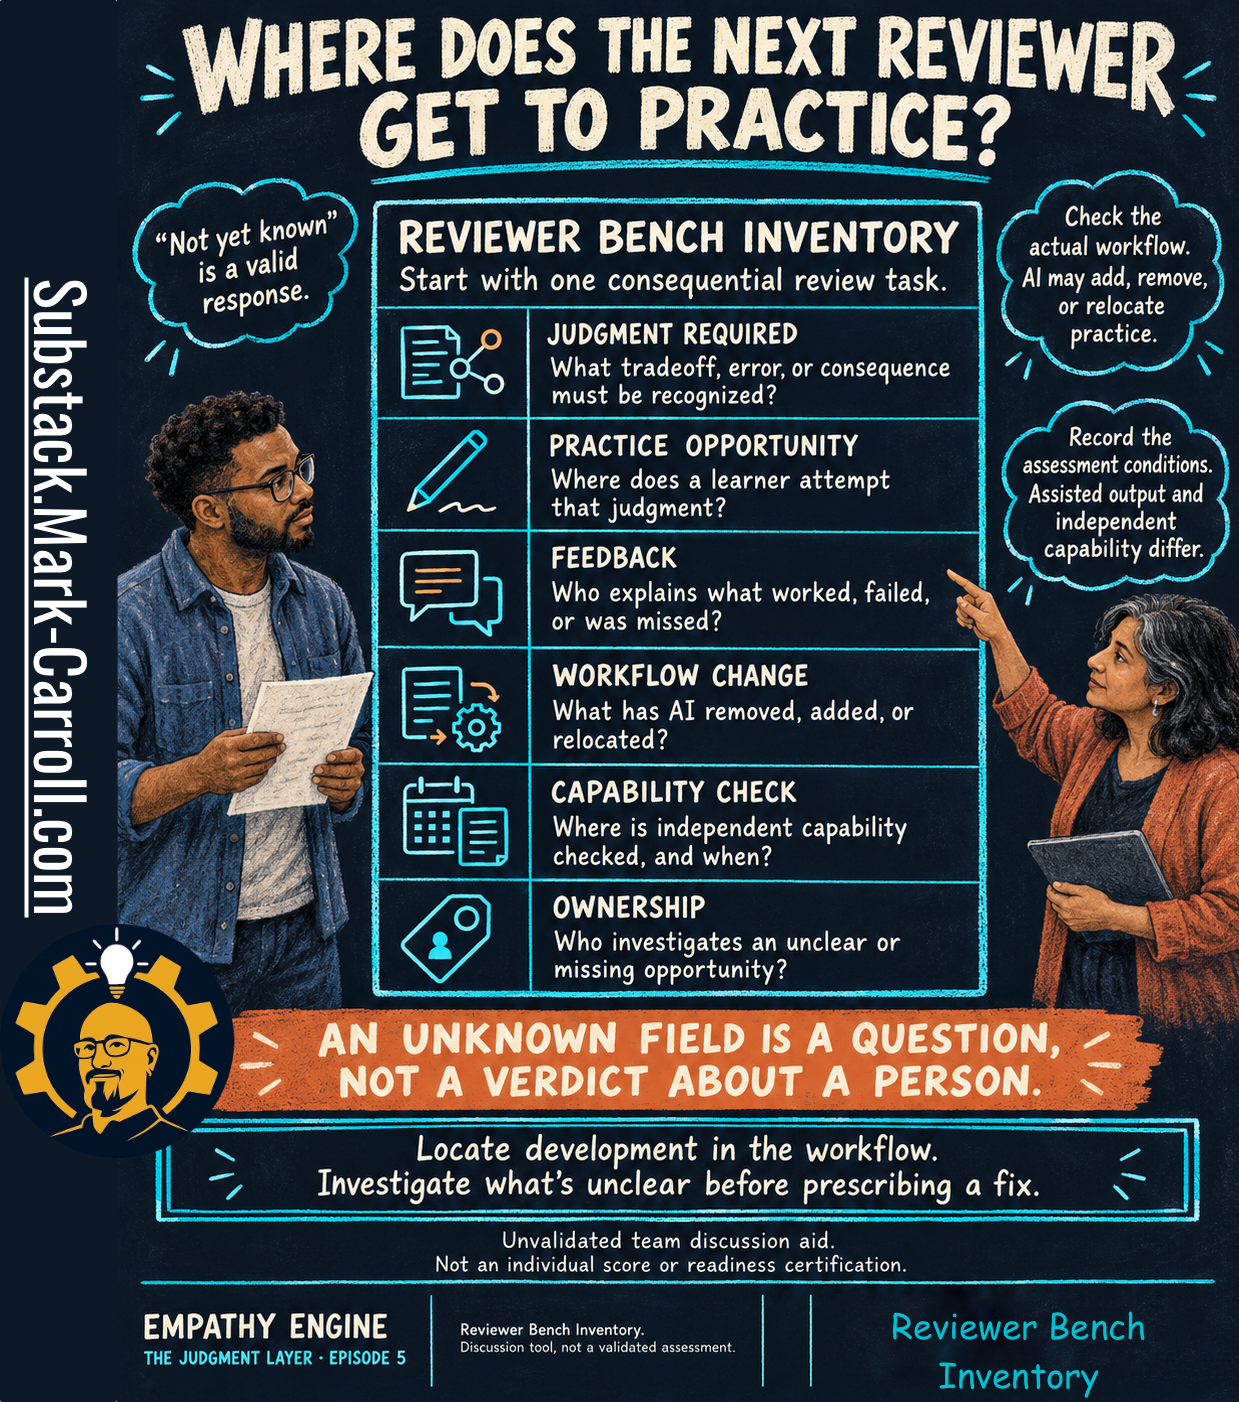
Judgment required: What tradeoff, error, or consequence must be recognized? Name the judgment, not the activity. “Review the pricing analysis” is a task; “notice when a comparison set quietly excludes the churned customers” is a judgment. Basis: Design inference.
Practice opportunity: Where does a learner attempt that judgment? The attempt might be independent, guided, or made right after studying a worked example; which fits depends on how far along the learner is. Watching someone else do it isn’t an attempt. Basis: Evidence from education (Sinha & Kapur; Kalyuga); applying it to workplace review is inference.
Feedback: Who explains what worked, failed, or was missed? A thumbs-up on the final version isn’t feedback on the attempt. Basis: Evidence from education (Wisniewski, Zierer & Hattie), with the Bacchelli and Bird review finding as context.
Workflow change: What has AI removed, added, or relocated? AI may remove practice, add it (an explainer, a faster feedback loop), or move it somewhere nobody’s looking. Basis: Design inference; the research reviewed for this issue didn’t establish how AI has changed these opportunities in professional review workflows.
Capability check: Where is independent capability checked, and when? Record the assessment conditions; if the only evidence is work produced with AI, write that down. Basis: Evidence; Shen & Tamkin and Bastani et al. show that assisted and unaided results can diverge, and Contractor & Reyes show that an immediate result and a one-week result are separate measurements.
Ownership: Who investigates an unclear or missing opportunity? Name a person, not a function. Basis: Design inference.
Two rules hold it together. “Not yet known” is a valid response. And an unknown field is a question, not a verdict about a person. The inventory locates development in the workflow and never grades the people inside it.
Done state: for one consequential task, the team can say where a learner attempts the judgment, where feedback happens, and where independent capability is checked, or it has named who will find out.
Constraint: this only works if “we don’t know where that happens” can be said out loud without anyone hearing it as a performance problem, theirs or the learner’s.
When I asked how newer colleagues were developing judgment, the answer was that they worked alongside experienced people. That sounded reasonable until I tried to locate an actual opportunity to make a call and get feedback on it. The experienced people were explaining decisions, correcting work, and keeping delivery moving. What I couldn’t find was a clear moment when the newer colleague offered their own assessment before someone supplied the answer.
Limitation: the inventory can’t prove anyone is learning, show what AI caused, or certify a reviewer as ready, and nobody has tested whether running it helps. It’s an unvalidated team discussion aid whose fields draw on separately studied practices, mostly from education. Investigate what’s unclear before prescribing a fix.
Run It on One Task
A heavy form is a form nobody finishes. Don’t start with the team or the career ladder; start with the next consequential review on the calendar.
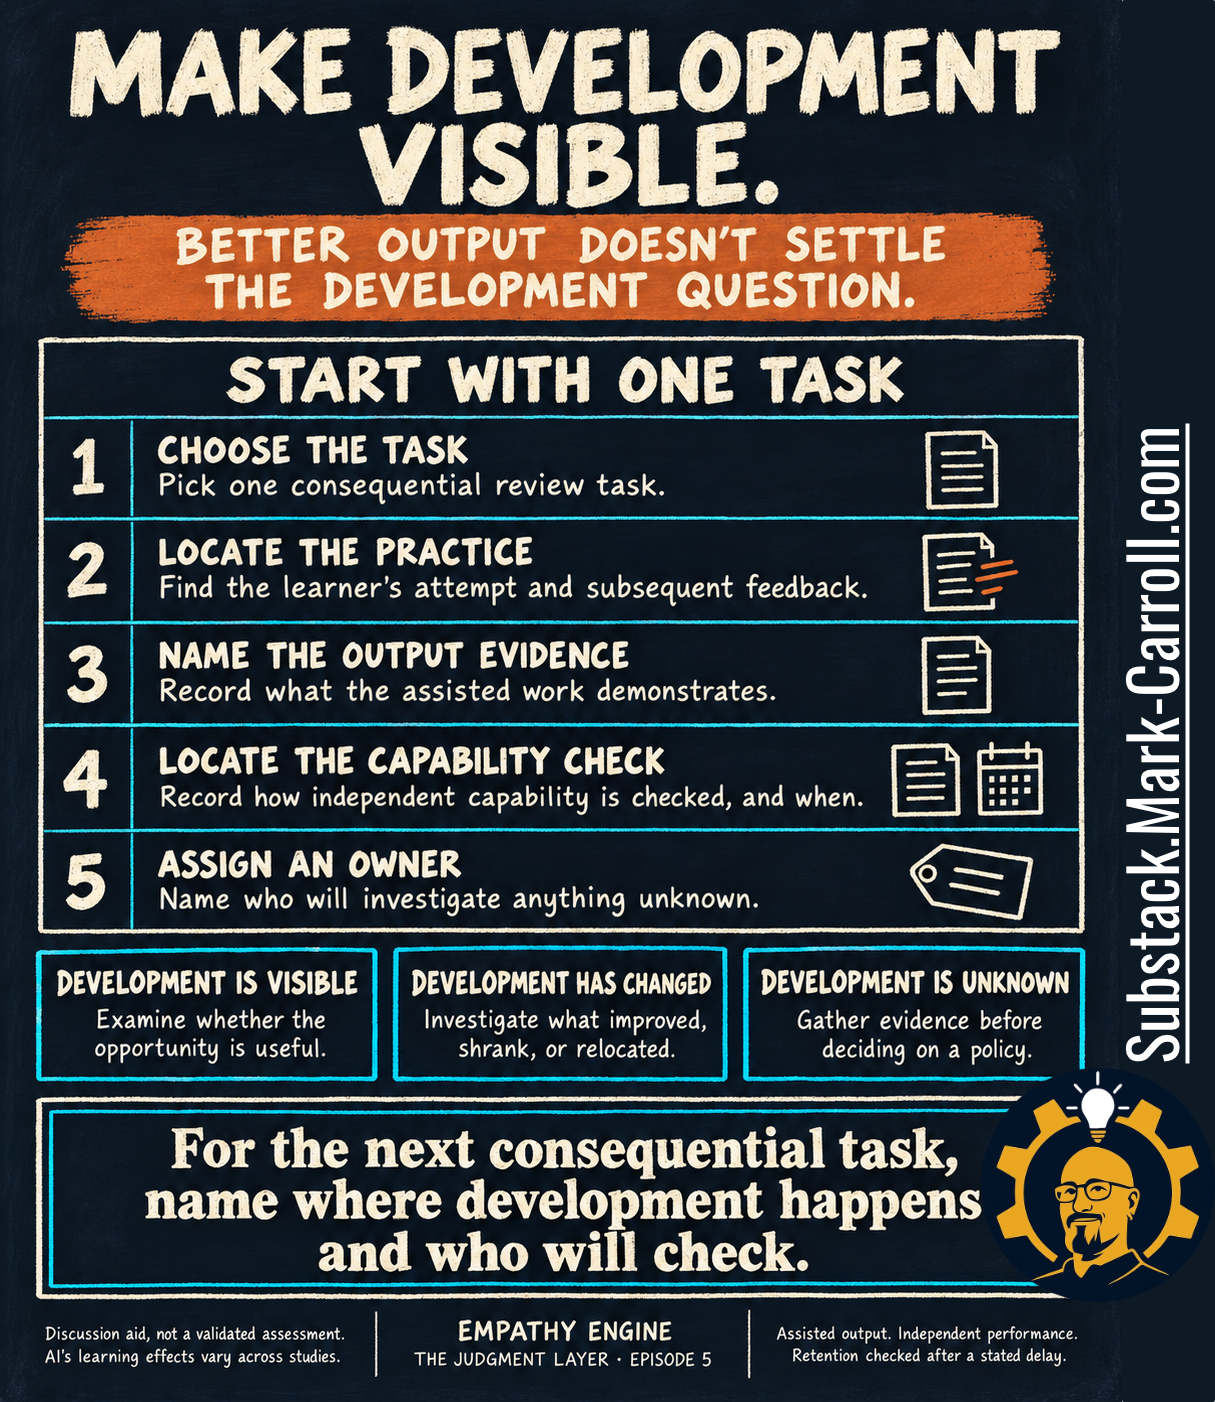
Choose the task. Locate the attempt and the feedback that followed it. Name what the assisted output demonstrates, and give it full credit. Record how and when independent capability is checked. Assign an owner for anything unknown.
The answers tend to point one of three ways. If development is visible, examine whether the opportunity is useful, because an attempt without informative feedback is just repetition. If it has changed, investigate what improved, shrank, or relocated; AI may have moved the practice somewhere better. If development is unknown, gather evidence before deciding on a policy; that beats a ban, a mandate, or a confident assumption. Better output doesn’t settle the development question. For the next consequential task, name where development happens, who will check, and the date they’ll check it.
🧪 What Holds Up
Primary claim label: Evidence for the separation between assisted output and independent capability; Design inference for the Reviewer Bench Inventory as a bundle.
Basis: In randomized studies, results measured with AI and without it can diverge: lower immediate unaided quiz scores after AI-assisted learning (Shen & Tamkin, Anthropic-affiliated preprint), and higher practice scores alongside lower exam scores under unguided AI (Bastani et al., PNAS). Large assisted gains (Brynjolfsson, Li & Raymond, QJE) were measured with AI in the room.
Counterpoint, labeled Evidence: Contractor & Reyes (preprint) found AI access raised unaided scores immediately and about one week later, and the support-agent outage results are consistent with durable learning on the job.
Scope and transfer limit: labs, classrooms, and crowd-worker samples, with follow-ups of about one week at most; the practice and feedback research is educational. None of it comes from Product, Program, Design, or Research teams.
What remains unknown: whether AI has changed attempts or feedback for newer professionals in real workplaces, what remains after months rather than days, and whether this inventory improves anything. It hasn’t been tested.
🛑 Do Not Use When
You want to rate, rank, certify, or monitor individual people. The inventory locates opportunities in a workflow; it says nothing about a person’s capability.
You’re looking for justification to restrict AI for newer staff, or to stop hiring them. The evidence here supports neither.
The task carries no consequential judgment. Inventory the reviews that matter, not every queue.
Judgment Seat
I’ve helped teams get work ready while also coaching the people producing it. Those responsibilities can pull against each other when a deadline makes it easier to supply an answer than explore someone’s reasoning. Once I’d stepped in, I needed to check what the colleague understood, because my contribution was now part of the finished work.
Who generated the work: increasingly, the tool, with a newer colleague steering it.
Who must understand it: that colleague, deeply enough to someday review someone else’s.
Who can stop it: the lead who decides whether the next consequential task includes an attempt, feedback, and an independent check.
Who pays if it is wrong: the lead who makes a readiness decision without knowing where the judgment was practiced or checked, and the colleague whose readiness was assumed.
🎁 Your Reviewer Bench Inventory
Your Reviewer Bench Inventory
Better work doesn’t tell us where people are learning to judge it. That’s why I’m gifting you this three-part kit: a guide, an editable workbook, and a printable field sheet. Use them to explore one important review task, find where practice and feedback happen, and plan what to check next. These tools guide a team discussion; they don’t score people or prove someone is ready to review.
The Practitioner Guide | PDF
This 10-page guide explains the six questions and how to use them with a team. It helps us choose a task where a missed error or poor choice would matter. Examples show the difference between a vague answer and one we can act on. There’s also guidance for running the meeting and handling gaps without blaming anyone.
The Working Workbook | Excel
This workbook gives the team a place to record answers and keep track of open questions. Four filled-in examples show how the inventory can work across different types of reviews. Separate tabs help us record practice, feedback, and how skills are checked with AI, without it, later, or on a new kind of task. A follow-up log holds the next steps, owner roles, and dates. The Bench Note brings the recorded answers together for the next conversation.
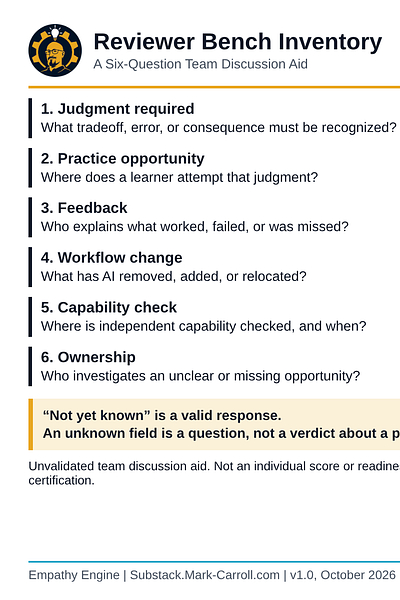
The Printable Field Sheet | A4 PDF
This one-page sheet puts all six questions within reach during a meeting. Print it and write down where people try making a judgment, get feedback, and have a chance to work on their own. It includes space for an owner role, an open question, and a follow-up date. “Not yet known” is a valid answer, so the team can name a gap without treating it as someone’s failure.
This Week
Three actions for the judgment owner: Name the judgment your next consequential review requires. Find the last time a newer colleague attempted it, and who gave feedback. Note where, if anywhere, their independent capability on that task gets checked without AI.
One action for the system owner: Decide in writing that “not yet known” is an acceptable answer on any development review, and that no inventory answer will be used to score an individual.
One action for learning and provenance: The next time AI-assisted work is praised in a review, add one line beneath it: what this shows about the work, and what it doesn’t show about the person.
📎 Forward This
Better work with AI doesn’t prove anyone got better without it. For your next consequential review, name where newer people practice, get feedback, and get checked without the tool.
🔚 Closing
The tool can improve the work on the first day.
Knowing whether the next reviewer is forming is still human work.
Next week, Episode Six widens the question from who can review to what counts as evidence. The working title, Whose Voice Is on the Slide?, points at “customer voice” that may be partly or wholly synthetic. Because knowing who can judge the work only matters if we also know where the evidence came from.

This question is part of the larger challenge behind my upcoming book, Collaborate Better: From Silos to Synergy, How to Build Unstoppable Teams. Better collaboration begins when context, ownership, and judgment travel with the work.
Learn more at CollaborateBetter.us.
Regards,
Mark 👋
Sources
Brynjolfsson, E., Li, D. & Raymond, L. (2025). Generative AI at Work. Quarterly Journal of Economics 140(2):889 to 942. https://academic.oup.com/qje/article/140/2/889/7990658
Shen, J. H. & Tamkin, A. (2026). How AI Impacts Skill Formation. arXiv:2601.20245v2. Anthropic-affiliated preprint. https://arxiv.org/html/2601.20245v2
Contractor, Z. & Reyes, G. (2026). Experimental Evidence on the Learning Impact of Generative AI. arXiv:2607.08849v1. Preprint. https://arxiv.org/html/2607.08849v1
Bastani, H. et al. (2025). Generative AI without guardrails can harm learning: Evidence from high school mathematics. PNAS. https://www.pnas.org/doi/10.1073/pnas.2422633122
Sinha, T. & Kapur, M. (2021). When Problem Solving Followed by Instruction Works: Evidence for Productive Failure. Review of Educational Research. https://eric.ed.gov/?id=EJ1308129
Kalyuga, S. (2007). Expertise Reversal Effect and Its Implications for Learner-Tailored Instruction. Educational Psychology Review 19, 509 to 539. https://www.uky.edu/~gmswan3/EDC608/Kalyuga2007_Article_ExpertiseReversalEffectAndItsI.pdf
Wisniewski, B., Zierer, K. & Hattie, J. (2020). The Power of Feedback Revisited. Frontiers in Psychology 10:3087. https://www.frontiersin.org/journals/psychology/articles/10.3389/fpsyg.2019.03087/full
Bacchelli, A. & Bird, C. (2013). Expectations, Outcomes, and Challenges of Modern Code Review. ICSE 2013. https://www.microsoft.com/en-us/research/wp-content/uploads/2016/02/ICSE202013-codereview.pdf
Brynjolfsson, E., Chandar, B. & Chen, R. Canaries in the Coal Mine? Stanford Digital Economy Lab, August 2026 update. https://digitaleconomy.stanford.edu/news/canariesaug26/
Humlum, A. & Vestergaard, E. NBER Working Paper w33777, revised March 2026 (Denmark). https://www.nber.org/system/files/working_papers/w33777/w33777.pdf
Valon new-hire AI policy: Business Insider, August 29, 2026, https://www.businessinsider.com/valon-ceo-bans-ai-most-new-hires-job-skills-2026-8; Forbes, August 30, 2026, https://www.forbes.com/sites/rachelwells/2026/08/30/an-ai-startup-bans-ai-and-tells-new-hires-learn-your-job/
Previous:

More Content to Discover:

Half Your Team Is Using AI. You Don't Know Which Half.

Intro If you read the piece we published last week on Leadership in Change, you saw the structural diagnosis: mandate pressure, decision collapse, intake collapse. Three failures that sit underneath almost every AI pilot that goes sideways. That piece mapped the architecture. What it did not cover is what happens on the human side of the same problem, wh…

A team can approve the work without knowing who could catch the next mistake. Think of one review: where did a newer colleague get to make the call and hear why it held up or fell short?
What gave us a real sign of learning, or left us guessing? Share an example without names or company details.